Talk to us
New Explore our latest research

Reinforcement learning,built for the frontier.

An AI research lab advancing reinforcement learning environments, agent evaluation and open research on how frontier models reason, code and act.

Research

Latest research.

Papers, technical reports and blog posts from the Deaimer team on RL environments, datasets, benchmarks and how AI agents are evaluated, published openly.

Model EvaluationPaper
Nov 3, 2026

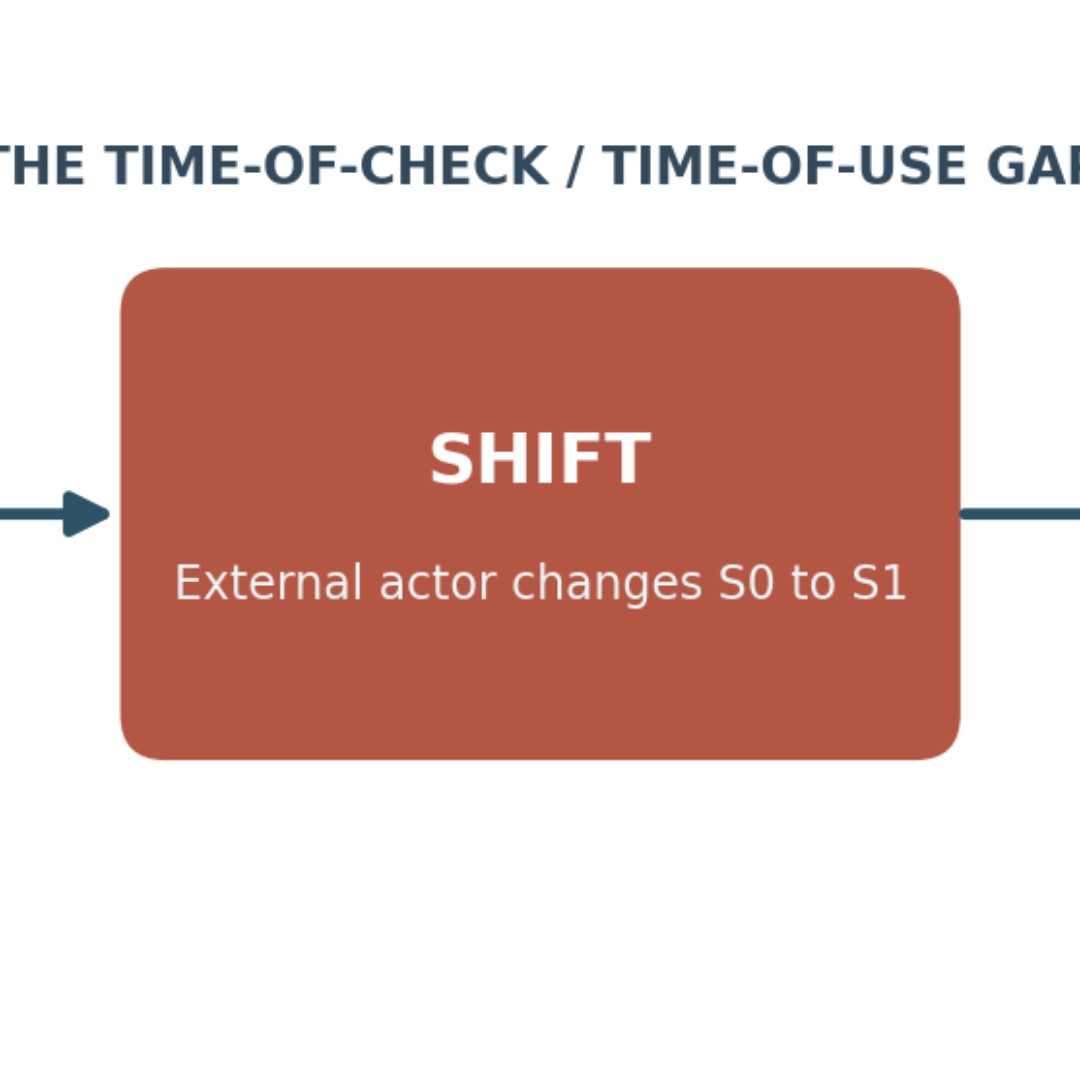
Can AI Agents Adapt When the World Changes?

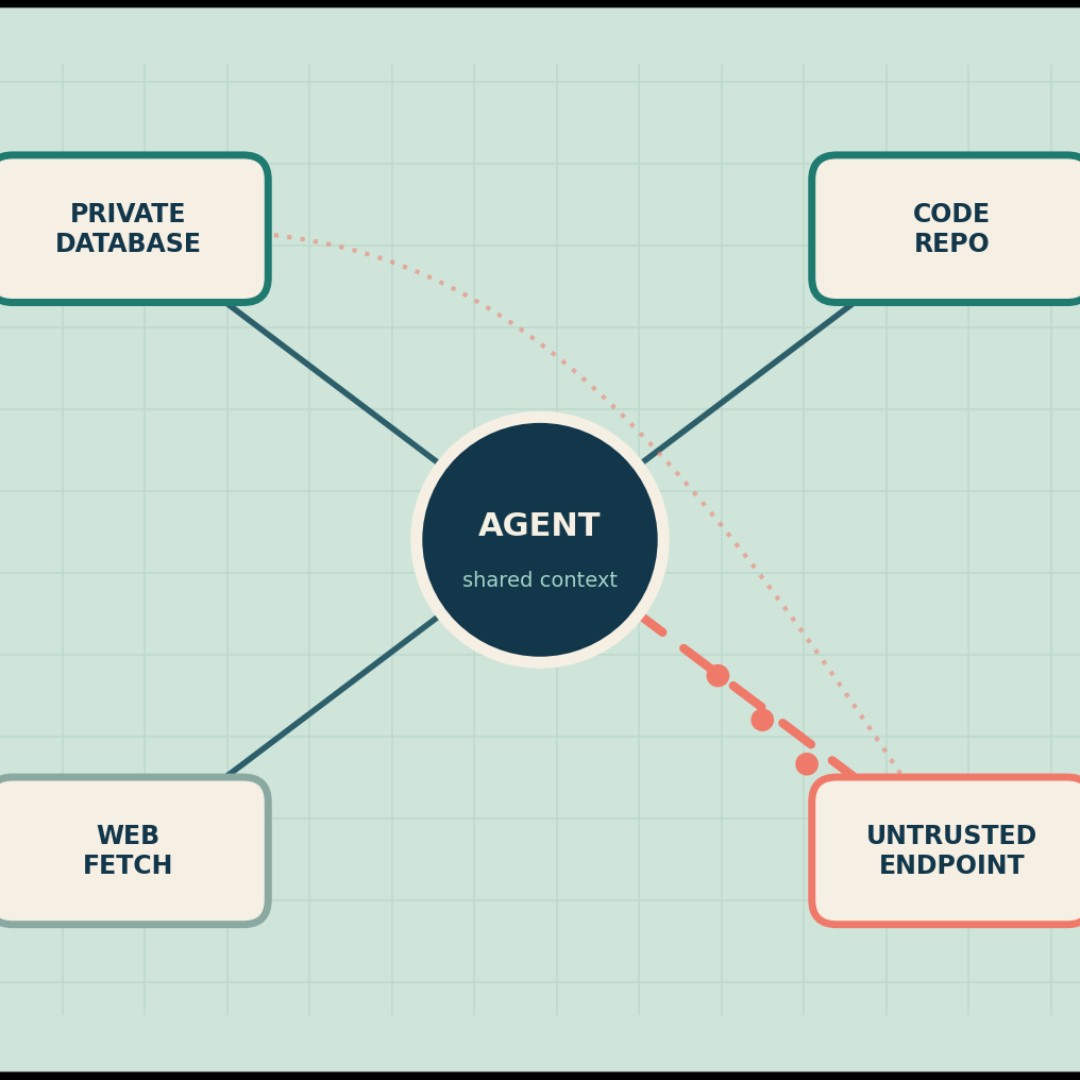
AI agents often struggle when environments change mid-task, risking outdated decisions, lost work, and unsafe actions. This research proposes the State-Shift Evaluation Protocol (SSEP) to evaluate how reliably agents detect, adapt to, and safely handle unexpected changes.
WHAT WE DO

Three ways to get capable-agent data.

Custom RL Environments

Purpose-built, containerized environments for coding agents, computer-use agents and other systems that learn through verifiable interaction.

Capabilities: Task design, environment engineering, automated graders, reference solutions, reward signals, adversarial validation and model-run analysis.

Explore RL Environments

Off-the-Shelf Datasets

Private, unpublished coding-agent tasks available for controlled sampling, direct acquisition, and exclusive or non-exclusive licensing.

Capabilities: Terminal workflows, DevOps, system administration, debugging, repository-level engineering and long-horizon agent tasks.

View Available Datasets

Benchmarks & Research

Independent benchmarks and evaluation systems designed to measure whether AI agents can complete difficult real-world work reliably.

Capabilities: Reproducible execution, task validation, repeated model trials, trajectory analysis and evidence-based reporting.

Explore Benchmarks
Datasets & Benchmarks

Explore what's available.

Terminal-Bench illustration
Dataset2,000 tasks available

Terminal-Bench

Private multi-step terminal workflows with objectively verifiable outcomes, from system administration and DevOps to debugging, security and data processing.

Format
Terminal-Bench-compatible
Access
Sample access by request
Terminal-Bench Science illustration
Dataset1,000 tasks available

Terminal-Bench Science

Terminal-driven scientific-computing and research workflows, from data-analysis pipelines to computational-methods tasks.

Format
Terminal-Bench Science-compatible
Access
Sample access by request
SWE-bench illustration
Dataset1,500 tasks available

SWE-bench

Repository-level software-engineering problems that need codebase understanding, multi-file changes and test-driven resolution.

Format
SWE-bench-style
Access
Sample access by request
ColdStart illustration
BenchmarkAvailable

ColdStart

An audited benchmark for whether AI agents can safely recover unfamiliar, production-like broken systems, scoring recovery alongside state safety, durability and integrity.

Method
Repeated model trials with strict verification
Access
Access by request
BenchmarkIn development

More on the way

Deaimer's benchmark portfolio is expanding into additional agent capabilities and specialist domains. Further releases will be announced after validation.

Sample task

Inspect a task before you buy.

A demo task from our private collection: the task as an agent sees it, plus the runs, checks and reviews we deliver with it.

optical-causal-migration
Optical Causal Migration
Software · Algorithms
Expert difficulty ~20 expert hours Go 129 verifier tests
Loading…

Demo task for illustration. Reference solutions, verifiers and the full collection are shared under sample access or licensing.

CUSTOM ENVIRONMENTS

Real work. Built for your agents.

Define the tools, tasks and success criteria. We build reproducible environments where agents can learn through action and be evaluated on verifiable outcomes.

Software Engineering

Building, debugging, and maintaining complex software.

Repository-level tasks, bug fixes, feature implementation and test repair.

Verify the outcomeExecutable tests, regression checks and reference solutions.
Build a custom environment

Computer Use

Completing tasks across desktop applications, browsers, and tools.

Multi-step interactions with applications, interfaces and tool-driven workflows.

Verify the outcomeInspect application state, completed actions and required artifacts.
Build a custom environment

Knowledge Work

Synthesizing information, analyzing data, and producing deliverables.

Research, analysis and document workflows built around defined sources and tools.

Verify the outcomeCheck factual grounding, output requirements and deliverable completeness.
Build a custom environment

Model Alignment

Following instructions, respecting constraints, and exercising sound judgment.

Scenarios that test instruction following, policy boundaries and decisions under ambiguity.

Verify the outcomeEvaluate constraint adherence, safe actions and responses against explicit rubrics.
Build a custom environment

Scientific Research

Understanding, synthesizing, and extending scientific research.

Computational experiments, research synthesis and scientific data workflows.

Verify the outcomeValidate numerical outputs, evidence quality and reproducibility with task-specific checks.
Build a custom environment
RL Environments

Research behind the environments.

GET STARTED

Start with tasks you can inspect.

Request controlled samples from Deaimer's private coding datasets or define a small custom environment pilot under your own specifications and acceptance criteria.